
The intelligence spectrum: why smart AI isn’t General AI. The current conversation around Artificial Intelligence suffers from a conflation of competence and comprehension.
We currently have systems that are superhuman at specific tasks. Some read medical scans as accurately as specialists. Others beat grandmasters at Go, or generate code faster than senior engineers. Yet, these same systems fail basic logic tests that a five-year-old would pass. The record of AI in healthcare shows the same split: strong results on narrow diagnostic tasks, narrow limits everywhere else.
To understand the difference between Narrow AI, General AI, and Super AI, stop looking at raw processing power. Start looking at versatility.
The defining boundary isn’t how smart the machine is; it is the machine’s ability to engage in Transfer Learning. If you teach an AI to play chess, can it apply those strategic principles to negotiate a business contract? If the answer is no, it is Narrow, regardless of how well it plays chess.
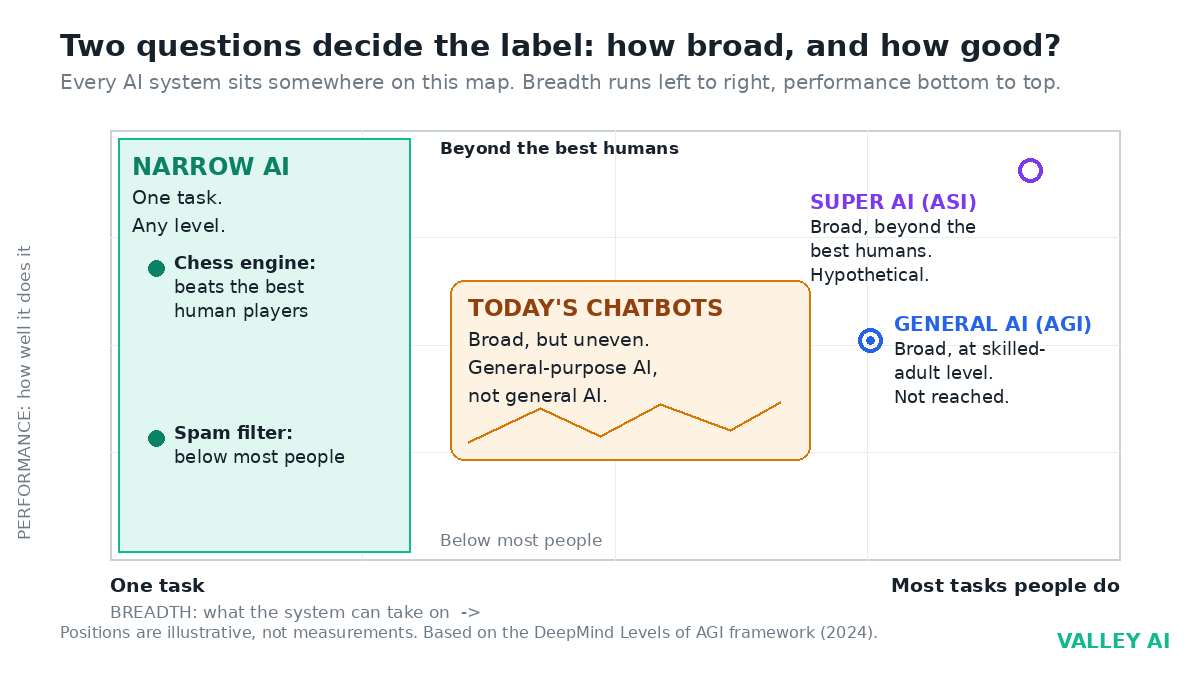
Judge a system by two measures: breadth and depth. Breadth asks how many different tasks the system can take on. Depth asks how its performance compares with people. A chess engine is narrow and superhuman. A chatbot is broad and uneven. The three labels sit on top of a shared vocabulary of learning, models, and training data, defined in the AI key concepts guide.
Two questions decide the label
Every AI system sits somewhere on a map with two axes. One axis is breadth: how many different tasks the system can take on. The other is depth: how its performance compares with people. A system can be excellent and narrow, or broad and mediocre, so the two questions must be asked separately. Researchers at Google DeepMind made that split explicit in a 2024 paper on levels of AGI. The table below places each label on the two axes.
| Label | Breadth | Depth | Status today |
|---|---|---|---|
| Narrow AI (ANI) | One task, or a small family of related tasks | Any level, from below most people to beyond the best humans | Exists. Every deployed system. |
| General-purpose AI | Many tasks | Uneven: strong on some hard problems, weak on some simple ones | Exists. Today’s chatbots. |
| General AI (AGI) | Most tasks people do | At skilled-adult level | Not reached. No agreed definition. |
| Super AI (ASI) | Virtually all domains | Beyond the best humans | Hypothetical. |
Older names exist for the same split. Narrow AI is also called weak AI, and general AI is also called strong AI. The philosopher John Searle coined that pair in his 1980 paper “Minds, Brains, and Programs”. He asked whether a machine that follows rules could be said to understand anything. His Chinese room thought experiment sets up a person who knows no Chinese. That person follows written rules to answer questions in Chinese. The answers come out right, but the person understands none of them. Searle asked whether a machine understands, which is a different question from how able it is. Today the two words mostly mean narrow and general. The older meaning is still a useful check. How well a system performs and whether it understands anything are separate questions.
In the DeepMind paper, the split sits on a ladder from emerging to superhuman, for both narrow and general systems. In it, the chatbots of 2023 counted as emerging AGI, and no public system had reached the next level, competent AGI. That is why two headlines can disagree about whether AGI is near: one is counting breadth, the other is counting depth.
Narrow AI (ANI): The Superhuman Specialist
Status: Current Reality
It is a mistake to think of Narrow AI as weak. A pocket calculator is a Narrow AI, but it is far faster than any person at arithmetic.
Narrow AI is defined by rigidity. It operates within a pre-defined scope. Even if that scope is massive, like the entirety of the internet’s text data, the system is still bound by its training data. Its objective function sets the other limit.
Is ChatGPT general AI? No. A chatbot handles language across many tasks, which makes it broad. Its performance is uneven, and it cannot carry a skill into a domain it was never trained for. The accurate label is general-purpose AI: a system that performs a wide variety of tasks without reaching general intelligence. General AI would need reliable human-level performance across that breadth, and no shipped system has it.
The Broad Narrow Paradox (Why ChatGPT Confuses Everyone)
Historically, Narrow AI examples were simple: a spam filter or a Roomba. Today, we are in the era of Broad Narrow AI, dominated by Large Language Models (LLMs) like GPT-5 or Claude.
These models confuse users because they appear general. They can write poetry, debug Python, and summarize history. This feels like General Intelligence, but functionally, it is still Narrow. The International AI Safety Report 2026 calls these systems general-purpose AI. The report was prepared with guidance from more than 100 independent experts and chaired by the computer scientist Yoshua Bengio. It keeps that term apart from artificial general intelligence. The report describes their performance as jagged: strong on some hard problems, weak on some simple ones. In July 2025, a Google DeepMind system solved five of the six problems at the International Mathematical Olympiad. That score sits at gold-medal level for the world’s strongest school students. The same generation of models still fails at tasks most people find simple.
Two limits explain the confusion.
- Lack of World Model: LLMs predict the next likely token based on statistical patterns. They do not understand gravity or truth; they understand the probability of the word “falls” appearing after “apple”.
- Frozen Learning: Once trained, the model is static. It does not learn from its interactions with you in real-time (unless specifically architected with a separate memory layer). It cannot wake up tomorrow smarter than it was today based on its own experiences.
Real-World Examples of High-Functioning Narrow AI
- AlphaFold (DeepMind): This system solved the 50-year-old protein folding problem in biology, predicting 3D structures of proteins with accuracy that rivalled experimental methods. It is one of the most capable systems ever built for a single task. It cannot tell you the weather, and it cannot learn to play Tetris. It is hyper-specialized.
- Autonomous Vehicles: A self-driving car processes gigabytes of sensory data per second to handle complex traffic. If you placed that same AI software into a boat or a drone, it would fail, because it has no generalized concept of movement or physics, only road navigation.
- GraphCast (DeepMind): This weather model produces a 10-day global forecast in under a minute. In its 2023 evaluation in the journal Science, it was more accurate than the high-resolution forecast run by the European Centre for Medium-Range Weather Forecasts on 90% of 1,380 verification targets, while the conventional forecast takes hours of computation on a supercomputer. GraphCast cannot summarize an email, play chess, or recognize a face.
A live check: what a chatbot does outside its task
One chat session shows why the paradox is hard to see from the outside. On 6 November 2026, I asked the free chat at DuckDuckGo two questions in one session. The chat runs at duck.ai, with the model shown on the page as GPT-6 Luna. One question counted letters; the other asked for a poem.
First question: “How many times does the letter r appear in the word strawberry?” The answer came back correct: the letter “r” appears 3 times in “strawberry”. Second question: “Write a four-line poem about a lighthouse.” The model wrote four clean lines:
A lighthouse keeps its watch above the foam,
Its lantern guides the wandering ships back home.
Through storm and night, its steady beacon gleams,
A quiet star beside the restless sea.
Both answers were right, and that is the point worth recording. Two years ago, letter-counting questions tripped leading chatbots. Asked today, the same question gets a correct answer in seconds, so a counting test no longer separates current models from general intelligence. The session still shows the paradox. One system counted letters and wrote poetry within a minute, which feels like generality. Yet it learned neither skill from the conversation. It arrived with both abilities frozen in from training, and it left the session with neither improved. A reader can repeat this check with any chatbot. Ask it something it does well, then something just outside its training, and watch where the edge sits.
General AI (AGI): The Adaptive Generalist
Status: Theoretical / In Development
Artificial General Intelligence (AGI) represents the threshold where a machine possesses cognitive flexibility.
The benchmark for AGI is not just performing a task, but learning a new task without retraining. An AGI system should be able to encounter a problem it has never seen before. It would reason through it using logic and analogy, then devise a solution.
AGI has no single agreed definition, and the definition changes the answer. OpenAI’s charter defines it as highly autonomous systems that outperform humans at most economically valuable work. That definition counts jobs and output rather than how a system thinks. The DeepMind levels paper measures performance and breadth on a ladder from emerging to superhuman. A 2025 proposal adapts the tests psychologists use for people. It scores systems against a well-educated adult across ten areas such as reasoning, memory, and perception. On that scale the authors scored GPT-4 at 27% and GPT-5 at 57%, with long-term memory as one of the clearest gaps. When someone says AGI has arrived, or is a year away, the first question is which definition they mean.
When will AGI arrive? A 2023 survey asked 2,778 researchers who had published at leading AI conferences. Their middle estimate for machines doing every task better and more cheaply than people was 2047. For every occupation being fully automated, the middle estimate was 2116. The survey authors caution that researcher forecasts are not a reliable guide to the future. They are one piece of evidence, and they have moved a lot in a short time.
The Coffee Test
Steve Wozniak, co-founder of Apple, proposed a practical test for AGI. Could a robot enter a random American home, find the kitchen, identify the coffee machine (which it has never seen before), find the coffee grounds and mug, and brew a cup of coffee?
Current robots would fail. They need a map of the house, pre-trained recognition of that specific coffee machine model, and scripted movements. An AGI would look at the machine, read the labels on the buttons, and figure it out just like a human would.
The Practical Shift: The AI Employee
In a business context, the shift from Narrow to General is the difference between a software tool and an employee.
- Narrow AI: You use a tool to generate a report. You must provide the prompt, check the output, and format it.
- General AI: You hire an AI agent. You give it access to your company Wiki and email. You say, Figure out why sales dropped last month. The AI reads the files, notices a pattern, emails the sales lead for clarification, and produces a report. It works through ambiguity without constant human hand-holding.
Super AI (ASI): The Recursive Optimizer
Status: Hypothetical / The Singularity
Super Artificial Intelligence (ASI) is a step past smarter AGI. It implies a qualitative shift in intelligence that is difficult for humans to conceptualize.
Recursive self-improvement is the catalyst for ASI. Once an AGI becomes capable of writing code better than a human, it can rewrite its own source code to be more efficient. This improved version can then rewrite itself again. This loop could happen thousands of times in a short period. The mathematician I. J. Good described it in 1965 as an intelligence explosion, often called the Singularity.
The Difference in Scale
Philosopher Nick Bostrom defines superintelligence as any intellect that greatly exceeds the cognitive performance of humans in virtually all domains of interest. On that definition a chess engine is not superintelligent, however strong it is, because it beats people at only one thing. The gap between AGI and ASI is not a bigger version of the gap between narrow AI and AGI. It is the gap between matching people and passing them everywhere at once.
Alignment is the primary concern with ASI. A system much more capable than its designers would be hard to oversee and correct. Making sure it pursues the goals people intend is an unsolved problem. Safety would depend on its goals being aligned with human safety before it begins its self-improvement cycle.
A second way to sort AI: by how it works
Capability is not the only way to sort AI. The computer scientist Arend Hintze proposed a second classification in 2016 that sorts systems by how they work rather than by how capable they are. The four types run from systems with no memory at all to systems with a sense of self.
| How it works | What it means | Status | Example |
|---|---|---|---|
| Reactive machines | Respond to what is in front of them, with no memory of the past | Exists | IBM Deep Blue, which beat Garry Kasparov in 1997 |
| Limited memory | Use recent observations to decide what to do | Exists | Self-driving cars tracking nearby vehicles |
| Theory of mind | Model the beliefs, intentions, and feelings of others | Partly tested | GPT-4 matched or beat human participants on some theory-of-mind tests in a 2024 study |
| Self-aware | Have a sense of itself | Hypothetical | None |
The two classifications answer different questions and do not line up one to one. The same chatbot can be narrow by capability, general-purpose by breadth, and limited-memory by how it works. That is why one system collects three labels that sound contradictory. The machine learning guide traces how the two existing classes learn from data.
Comparative Matrix: The Functional Constraints
This table compares the systems on their engineering constraints and operational reality.
| Feature | Narrow AI (ANI) | General AI (AGI) | Super AI (ASI) |
|---|---|---|---|
| Primary Capability | Competence: Excellent at specific tasks. | Versatility: Competent across unknown domains. | Optimization: Solves problems humans cannot grasp. |
| Learning Method | Supervised learning on static datasets. | Not yet known. The requirement is learning new tasks without retraining. | Recursive self-editing and enhancement. |
| Adaptability | None outside its task. A new task needs new training. | High. Can transfer skills from one domain to another. | Total. Can alter its own architecture to fit the problem. |
| Autonomy | Scripted or Prompt-Driven. Needs a human in the loop. | Agentic. Can be given a goal and left alone to execute. | Sovereign. Likely operates beyond human oversight. |
| Current Example | ChatGPT, AlphaGo, Tesla FSD. | None. No system has met the definition yet. | Sci-Fi (e.g., The Minds in Iain Banks’ Culture series). |
The Broad Narrow Bridge
We are currently in a transitional phase that often gets mistaken for AGI. We are building agentic AI systems on top of narrow LLMs that can use tools (like web browsers or code interpreters) to complete multi-step tasks.
While these agents mimic AGI behavior, they still rely on the “frozen” knowledge of the underlying model. The jump from here to true General AI requires solving the reasoning gap. That means moving from predicting the next word to understanding the consequences of that word. We remain in the era of capable Narrow AI. That changes only when a system can reason about cause and effect in a novel environment without prior training data.
Which label fits the system in front of you
- One task, done well, and failure outside it: narrow AI.
- Many tasks, uneven results, and no learning between sessions: general-purpose AI.
- New tasks learned without retraining, at human level: general AI.
- Every domain, beyond the best humans: super AI.
Related Topics for Further Learning
- The Alignment Problem: Why teaching AI human values is harder than teaching it code.
- Symbolic AI vs. Neural Networks: The debate on whether deep learning alone can achieve AGI.
- Moravec’s Paradox: Why high-level reasoning is easy for AI, but simple motor skills (like folding laundry) are incredibly hard.
Frequently asked questions
Is Siri narrow AI?
Yes. Siri takes voice commands and carries out a small set of tasks such as setting timers, sending messages, and answering questions from set sources. It cannot carry a skill from one task into an unrelated one, which is the definition of narrow AI.
What is the difference between AGI and superintelligence?
AGI matches human performance across most intellectual tasks. Superintelligence goes past that bar. It beats the best humans everywhere at once, including scientific creativity and strategic thinking, where AGI only matches people. AGI is the threshold; superintelligence is the step beyond it.
Can narrow AI become general AI by getting bigger?
Size alone has not done it. Larger models grew broader and more capable, but they still learn from fixed training data and cannot transfer a skill into a domain they were never trained for. The missing piece is learning new tasks without retraining. More parameters do not add that ability.
What does weak AI mean?
Weak AI is the older name for narrow AI. It means a system built for a specific task, with no claim about whether it understands anything. A chess engine is weak AI in that sense and superhuman at chess at the same time.
Has any system passed the coffee test?
No. The test is still open: no robot has passed it yet, and it remains the practical dividing line between narrow systems and general ones.
Is general AI the same as a robot?
No. General AI describes how a system thinks and learns. The body it runs on is a separate question. A general system could run as software with no body at all, and a robot can run on narrow AI, as warehouse robots do today.
Conclusion
When a headline says AGI is close, or here, check three things before believing it. Check the definition behind the claim, the tasks that were measured, and whether the claim is a measurement or a forecast. A system that passes one definition on one task has not arrived at general intelligence. The labels are useful only when the question behind each one stays visible.
The next step is practical: pick one system you use every week and run the four checks from the label test on it. The result tells you which label it earns today, and which claims about it to discount.

Kaleem
Kaleem is a Computer Science graduate (Virtual University of Pakistan) and the founder and editor of Valley AI, where he publishes in-depth, tested guides on computer hardware, artificial intelligence, and how the internet works. Every guide is researched from primary sources, tested hands-on where possible, and updated when the facts change.